Trainable Document Classifier[source]
The eds.doc_classifier component is a trainable document-level classifier. It predicts attributes of the document as a whole (its type, a principal diagnosis, the set of topics it covers) from a single pooled document embedding, and stores each prediction in a Doc._ extension.
The component is configured with one head per predicted attribute, given as a dict of options: a single-label head when a document has exactly one label, a multi-label head (multi_label: true) when it has a variable-length set of them.
Architecture
A document embedding component, such as eds.doc_pooler, turns the document into a single vector, which is fed to each head. A head owns its own MLP and label set, and writes to the Doc._ attribute it is named after. A single-label head is trained with a cross-entropy loss and decoded with an argmax, a multi-label head with a binary cross-entropy loss and decoded by keeping every label whose probability is at least its threshold. At training time the per-head losses are aggregated into a single loss, weighted by each head's loss_weight.
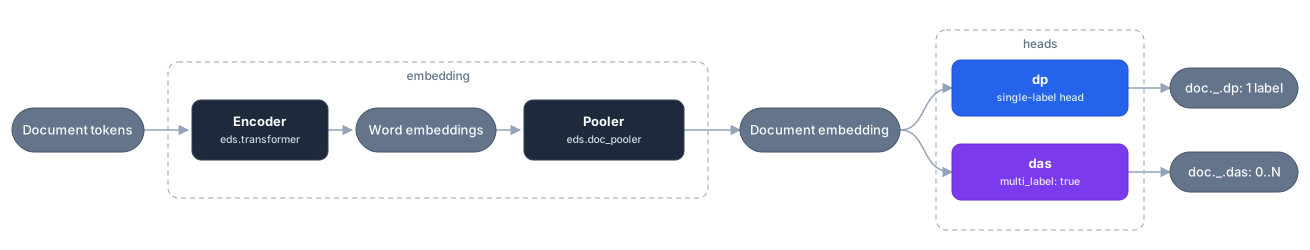
Examples
The pipeline below predicts the principal diagnosis of a hospital stay (exactly one per document, so a single-label head) and its associated diagnoses (a set, so a multi-label head). Each head is keyed by the name of the attribute it fills in.
import edsnlp, edsnlp.pipes as eds

nlp = edsnlp.blank("eds")
nlp.add_pipe(
    eds.doc_classifier(
        embedding=eds.doc_pooler(
            pooling_mode="mean",
            embedding=eds.transformer(
                model="hf-internal-testing/tiny-random-bert",
                window=128,
                stride=96,
            ),
        ),
        heads={
            # the principal diagnosis: exactly one per document
            "dp": {"labels": ["C34", "I21"]},
            # the associated diagnoses: a set, of any size
            "das": {
                "labels": ["E11", "I10", "N18"],
                "multi_label": True,
                "threshold": 0.5,
            },
        },
    ),
    name="doc_classifier",
)

doc = nlp("Compte rendu d'hospitalisation.")
print(doc._.dp in ["C34", "I21"], isinstance(doc._.das, list))
# Out: True True
To predict a single attribute, keep only the corresponding head.
labels may also be the path to a JSON file holding the list of labels, or to a text file with one label per line, which is convenient for large label sets. It can also be left out entirely, in which case the labels are inferred from the gold data during nlp.post_init(...). Once saved, the model no longer depends on these files: the labels are stored with the model.
A document whose gold value is None for a head does not supervise it. A corpus annotated only for the principal diagnosis can therefore be mixed, in the same training run, with one annotated for everything.
To train the model, refer to the Training API documentation and to the document classifier tutorial.
Extensions
The eds.doc_classifier pipeline declares one extension on the Doc object per head, named after the head:
doc._.<head>: the label predicted by the head, a string for a single-label head and a list of strings for a multi-label one.
When store_probs is set, it also fills doc._.prob, a dict mapping each head name to a {label: probability} dict.
Parameters
| PARAMETER | DESCRIPTION |
|---|---|
nlp | The pipeline the component belongs to. TYPE: |
name | Component name. TYPE: |
embedding | Document embedding component, which returns one embedding per document, such as TYPE: |
heads | The heads of the classifier, keyed by the name of the
TYPE: |
store_probs | Whether to store the per-label probabilities of each head in TYPE: |
probs_topk | Only store the probabilities of the TYPE: |
probs_threshold | Only store the probabilities greater than or equal to TYPE: |
Authors and citation
The eds.doc_classifier pipeline was developed by AP-HP's Data Science team.